Technical SEO and crawl discovery
How Do XML Sitemaps Work? A Practical SEO Guide
An XML sitemap is a UTF-8 encoded file that lists the canonical URLs a website wants search engines to discover. Search engines fetch the file, extract its URLs and metadata, then add eligible URLs to their crawl queues. A sitemap can improve discovery and recrawl scheduling, especially on large, new or weakly linked sites. It does not guarantee crawling, indexing, rankings or inclusion in AI-generated answers.
TL;DR
Key Takeaways
- A sitemap is a discovery signal, not an indexing command or ranking factor.
- Include only absolute, canonical, indexable URLs that return a successful response.
- Each sitemap is limited to 50,000 URLs or 50 MB uncompressed.
- Google ignores changefreq and priority, but may use accurate lastmod values.
- Large sites should segment sitemaps by content type, template or business function.
- Submitted versus indexed differences are diagnostic clues, not necessarily errors.
- Internal links, canonical tags, robots directives and content quality must agree with the sitemap.
- Measure sitemap performance through search engine reports, crawl logs and indexation cohorts.
How XML sitemaps work
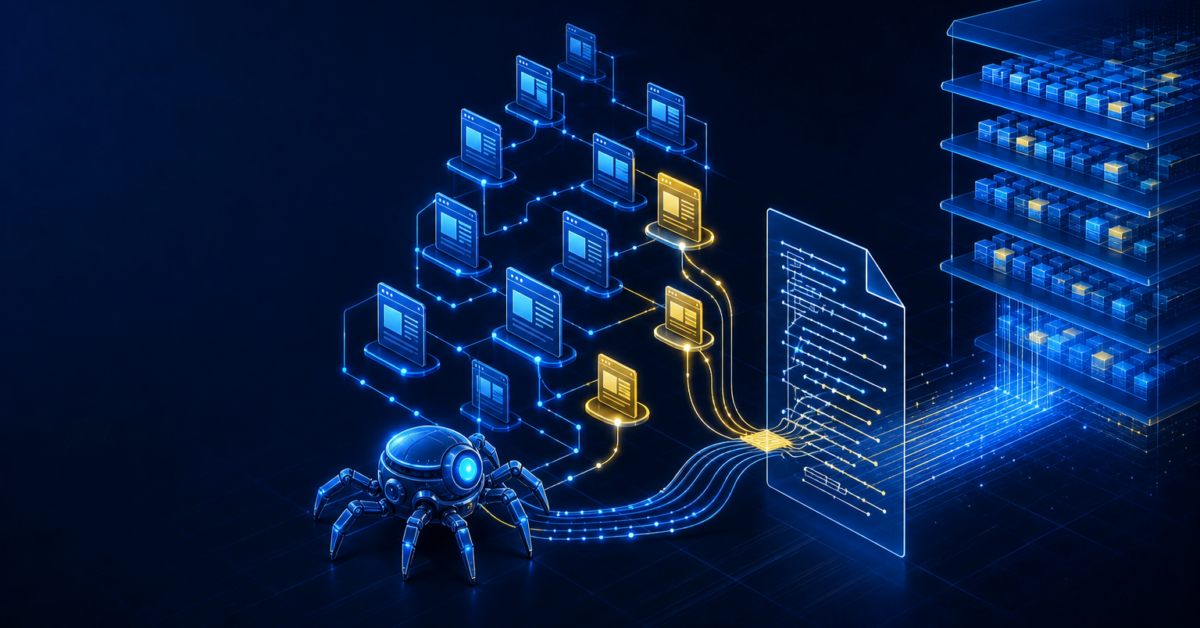
A search engine first discovers the sitemap through Search Console, Bing Webmaster Tools, a robots.txt declaration or a previously known sitemap index. It downloads the XML, reads each loc value and may use reliable metadata such as lastmod when deciding what to recrawl.
The listed URLs become candidates for crawling. The crawler still applies its own scheduling, resource and quality systems. After fetching a page, the search engine evaluates response status, robots controls, canonical signals, duplication, rendering, content usefulness and other factors before deciding whether to index it.
This creates an important distinction: discovery is not crawling, and crawling is not indexing. Google explicitly describes sitemap submission as a hint. A URL can appear in a valid sitemap yet remain uncrawled, excluded as a duplicate or rejected from the index.
The sitemap also does not replace navigation. Search engines and users still need crawlable internal links that establish hierarchy, context and relative importance.
What an XML sitemap should contain
The basic protocol requires UTF-8 encoding, a urlset container and one url element per entry. Each entry needs an absolute loc URL, including the protocol and hostname. XML entities must be escaped correctly.
A minimal entry can be represented as <url><loc>https://www.example.com/page/</loc></url>. The optional lastmod value should reflect a meaningful page update, not the time the sitemap was regenerated.
- Include: canonical pages returning a successful response that are intended for search results.
- Exclude: redirects, error pages, noindex URLs, blocked pages, duplicates, internal search results and low-value parameter combinations.
- Google ignores: the priority and changefreq fields.
- Useful extensions: image, video, news and localized URL metadata when the content qualifies.
One sitemap can contain no more than 50,000 URLs and must be no larger than 50 MB when uncompressed. A sitemap index connects multiple sitemap files for larger inventories.
Which websites benefit most
Any site can use an XML sitemap, but the incremental value differs. A small, well-linked brochure site may already expose every page through navigation. A marketplace with millions of product, category and location URLs has a much harder discovery problem.
| Site condition | Likely value | Recommended design |
|---|---|---|
| New domain with few external links | High discovery value | One clean sitemap submitted immediately |
| Large ecommerce catalog | High crawl and diagnostic value | Separate products, categories and editorial content |
| Publisher with frequent updates | High freshness value | Accurate lastmod plus eligible news metadata |
| Site with orphan or poorly linked pages | Temporary discovery benefit | Add sitemap entries, then repair internal linking |
| Small, stable service site | Moderate convenience | One automatically maintained file |
| Site with duplicate parameter URLs | Potentially harmful if unfiltered | Publish canonical URLs only |
Google particularly identifies large sites, new sites, sites with rich media and sites with weak internal linking as likely beneficiaries. A sitemap can expose an architecture problem, but should not become a permanent substitute for fixing it.
How to create and submit a sitemap
- Define eligibility. Start with URLs that are canonical, indexable, useful and returning a successful response.
- Choose generation logic. A CMS plugin is usually sufficient for a small site. Large or frequently changing sites should generate sitemaps from a database, publishing system or product feed.
- Segment intentionally. Separate products, categories, articles, videos, locations or language groups when that separation will support diagnosis.
- Validate the output. Check XML syntax, encoding, absolute URLs, response codes, canonical tags and robots directives.
- Host it predictably. Root-level hosting usually gives the clearest scope. Follow same-site and directory rules when using sitemap indexes.
- Declare and submit it. Add the location to robots.txt and submit it through Google Search Console and Bing Webmaster Tools.
- Automate maintenance. Add new eligible URLs promptly and remove redirects, deletions and noindex pages.
Do not rely on the retired Google sitemap ping endpoint. Google deprecated that submission method in 2023. Use stable sitemap locations, robots.txt discovery and search engine webmaster platforms instead.
Choose the right sitemap architecture
The best structure is not simply the smallest number of files. It is the structure that makes discovery and indexation measurable. A single 40,000 URL file may be valid, but it can conceal whether a specific product template or regional directory is failing.
Practical decision rules
- Use one sitemap when the site is small and its pages have similar publishing and indexation behavior.
- Split by content type when products, articles, locations or videos use different templates.
- Split by lifecycle when active products, discontinued products and archives require separate analysis.
- Split by language or region when international sections have independent ownership or release schedules.
- Avoid hundreds of tiny files unless they provide a real operational or diagnostic advantage.
A sitemap index can reference up to 50,000 sitemap files. Google also documents a Search Console limit of up to 500 submitted sitemap indexes per property. These are ceilings, not design targets.
For enterprise sites, keep a versioned record of sitemap counts, additions and removals. Sudden changes can reveal publishing failures before traffic declines become visible.
Align sitemaps with canonicalization and internal linking
A URL sends its clearest signal when four systems agree: the sitemap includes it, internal links point to it, its canonical tag selects it and its robots directive permits indexing. Conflicts make search engines spend time resolving which signal to trust.
For example, listing a product URL while its canonical points to a category page is not a productive request for indexation. Nor should a noindex page remain in the sitemap. Google may report these conflicts through exclusion categories, but prevention is more efficient than repeated cleanup.
Use a hub-and-spoke architecture for important topic groups. A crawlable hub should link to its supporting pages, while those pages link back to the hub and to closely related resources where useful. The sitemap then reinforces a discoverable graph rather than acting as the only path to content.
For consolidation projects, remove obsolete URLs from the sitemap after implementing the appropriate redirect or deletion response. Update internal links and canonicals at the same time. Keeping old URLs listed can prolong unnecessary crawling and obscure migration diagnostics.
Diagnose sitemap, crawling and indexing problems
Start with the symptom, then identify the stage where the process failed.
| Symptom | Likely checks | Next action |
|---|---|---|
| Sitemap cannot be fetched | Response status, DNS, robots controls, redirects, file size | Return a stable successful response and resubmit |
| URLs discovered but not crawled | Internal links, server capacity, crawl logs, URL duplication | Strengthen paths and remove crawl traps |
| Crawled but not indexed | Content value, duplication, canonical choice, rendering | Improve or consolidate affected pages |
| Submitted URL is a redirect | Generator lag or migration mapping | Replace it with the final canonical URL |
| Indexed count suddenly falls | Template directives, outages, canonical changes, inventory removals | Compare cohorts and deployment history |
| lastmod is ignored | Dates change without meaningful page edits | Generate dates from verified content updates |
Search Console totals should be treated as diagnostic summaries rather than a perfect census. Compare them with Bing reports, server logs and your own URL inventory. Logs can show whether Googlebot or Bingbot fetched a sitemap, which listed URLs received visits and how frequently important cohorts were revisited.
Useful KPIs include valid sitemap URLs, stale or ineligible entries, crawler fetch rate, median time from publication to first crawl, indexed share by sitemap cohort and organic landings from newly published URLs.
Special cases and common failure modes
International sites: localized alternates can be expressed in sitemap annotations, but each version should be canonical and indexable. Keep hreflang relationships reciprocal and consistent with page markup.
Images, video and news: use the relevant extension only when the page and media satisfy search engine requirements. Extra markup does not create eligibility by itself.
Migrations: create a clean sitemap for destination URLs and retain a temporary old URL sitemap when it helps monitor redirect crawling. Remove that migration aid after search engines have processed the move.
Faceted navigation: do not export every filter combination. Include only facets intentionally selected as canonical search landing pages.
Headless sites: generate the sitemap from the canonical content inventory, not merely from client-side routes. Verify that listed pages render meaningful content to crawlers.
Plugin failures: watch for cached files, deleted posts that remain listed, incorrect protocol or hostname values and timestamps that change on every request. Automated generation still requires automated validation.
What sitemaps mean for AI search systems
XML sitemaps can help conventional search crawlers discover pages that may later become eligible for Google AI Overviews, AI Mode, Bing results or Copilot experiences. They do not make a page quotable, prove its claims or guarantee selection in an AI-generated response.
Answer systems generally benefit from the same foundations as search: accessible pages, stable canonical URLs, clear entities, concise definitions, explicit relationships and verifiable evidence. Internal links should connect the main topic hub to pages answering likely follow-up questions. This supports query fanout without producing thin pages for every wording variation.
For ChatGPT and other systems, discovery mechanisms, licensed indexes and crawler access can vary. It remains uncertain how much any individual system relies on submitted XML sitemaps. Treat the sitemap as infrastructure, not an AI optimization shortcut.
A useful strategy is to pair crawlable architecture with original assets that create citation demand, such as datasets, comparison tables, testing methodologies, statistics pages and expert contributions. The sitemap helps those assets get found. Their evidence and usefulness make them worth retrieving or citing.
What is proven, accepted and uncertain
Proven by protocols and official documentation
- Sitemaps communicate URL locations and optional metadata.
- Submission is a hint and does not guarantee indexing.
- Google ignores priority and changefreq.
- Accurate lastmod may influence recrawl scheduling.
- File size and URL count limits apply.
Strong practitioner consensus
- Clean, segmented sitemaps make enterprise indexation problems easier to isolate.
- Internal links and consistent canonical signals matter more than repeatedly resubmitting the same file.
- Database-driven generation is safer than manual maintenance for changing inventories.
Still uncertain or site dependent
- The exact crawl improvement produced by a sitemap varies with authority, architecture, server health and content demand.
- No reliable public formula predicts how much accurate lastmod changes crawl frequency.
- The direct role of sitemaps in selection by individual generative AI systems is not publicly established.
Anecdotal discussions among technical SEO practitioners report that cleaning sitemaps often improves discovery and troubleshooting, but does not rescue thin, duplicate or weakly linked pages. These reports are useful operational observations, not causal proof.
FREQUENTLY ASKED QUESTIONS
SEO Questions Answered
Does an XML sitemap improve rankings?
Not directly. A sitemap can help a search engine discover and recrawl eligible pages, which is necessary before ranking can occur. Ranking still depends on relevance, quality, links, usability and other signals.
Does every website need an XML sitemap?
No, but most sites benefit from having one because it is inexpensive discovery and diagnostic infrastructure. It is most valuable for large, new, frequently updated, media-rich or poorly linked sites.
How often should an XML sitemap be updated?
Update it whenever eligible URLs are added, removed or materially changed. Automated generation is preferable. Do not change lastmod merely because the sitemap was regenerated.
Should noindex pages appear in a sitemap?
No. A sitemap should represent URLs intended for indexing. Including a noindex URL sends conflicting signals and makes reporting less useful.
Can a sitemap contain redirected URLs?
It should not contain them during normal operation. Replace redirected entries with their final canonical destinations. A temporary old URL sitemap can be useful for monitoring a controlled migration.
Where should sitemap.xml be located?
Root-level placement, such as https://example.com/sitemap.xml, is usually simplest. Other locations can work, but directory scope and cross-site rules must be respected.
What is the difference between a sitemap and robots.txt?
A sitemap identifies URLs a site wants search engines to discover. Robots.txt controls crawler access to specified paths. A robots.txt file can also declare the sitemap location.
Why are sitemap URLs discovered but not indexed?
Possible causes include weak content, duplication, an alternate canonical, rendering problems, limited crawl demand or insufficient internal links. Inspect a sample from each affected sitemap cohort rather than resubmitting blindly.
Should priority and changefreq be included?
They are optional protocol fields, but Google says it ignores them. Accurate lastmod data is more useful. Removing unsupported or unreliable metadata also keeps generation logic simpler.
Can one sitemap cover multiple domains?
The standard protocol generally expects URLs from one host. Search engines document specific cross-site submission and verification arrangements, but separate, verified sitemap structures are usually easier to govern.
RESEARCH SOURCES
Sources and Verification
- Google Search Central, Sitemaps OverviewOfficial guidance on discovery benefits, suitable site conditions and the fact that sitemap submission is only a hint.
- Sitemaps.org ProtocolPrimary protocol specification covering required elements, XML escaping, host restrictions and optional metadata.
- Bing Webmaster Tools, SitemapsOfficial Bing documentation for supported sitemap formats, submission and processing.
- Bing Webmaster Blog, Sitemap Index CoverageExplains Bing reporting for inspecting sitemap and index coverage differences.
- Microsoft Learn, Bing Webmaster ToolsMicrosoft documentation for Bing site management and webmaster diagnostics.
- Library of Congress, Sitemaps APIA public-sector example of sitemap traversal for mapping a large web resource inventory.
- ResourceSync: The NISO Open Framework for Web-Scale Resource SynchronizationResearch describing XML Sitemap-derived synchronization approaches for large resource collections.
- Search.gov, How Search Engines Index Your WebsiteGovernment search guidance explaining discovery, crawling and indexing concepts.
- Search Engine Journal, XML Sitemaps GuideIndependent practitioner synthesis on sitemap auditing, extensions, freshness and indexation diagnosis.
- Reddit TechSEO, XML Sitemap Practitioner DiscussionAnecdotal community observations about clean sitemaps, discovery and the limits of sitemaps for weak content.
- ETSI, Robots and Sitemap DevOps ContributionTechnical contribution discussing operational management of robots and sitemap resources.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Google Search Central, Build and Submit a SitemapOfficial requirements for formats, canonical URLs, absolute locations, encoding and sitemap limits.
- Research sourceConsulted during live web research for this page.
- Bing Webmaster GuidelinesOfficial guidance on canonical URLs, freshness metadata, redirects and deleted URLs.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Google Search Central, Manage Large SitemapsOfficial instructions for sitemap indexes, placement rules and large URL inventories.
SEOS.CO EXPERT MATCH
Ready to Find the SEO Partner That Can Win Your Market?
Tell us your market, goals and growth targets. SEOS.co will help narrow the field and connect you with a serious SEO partner built for the opportunity.