Google Indexing Diagnosis and Recovery
Why Is Google Not Indexing My Pages?
Google may not index a page because it cannot access or render the URL, detects a noindex directive, selects another canonical, interprets the page as a soft 404, or decides the content is duplicate or insufficiently valuable. A sitemap or successful crawl does not guarantee indexing. Start with URL Inspection, compare the live and indexed versions, verify status codes and directives, then evaluate canonical consistency, rendered content, internal links, uniqueness and search intent. Fix patterns across page groups before repeatedly requesting indexing.
TL;DR
Key Takeaways
- Crawling, indexing and ranking are separate decisions. A successful crawl does not mean Google will store or rank the page.
- Check the exact Search Console exclusion status before changing content, links or technical settings.
- Robots.txt, noindex directives, canonical tags, redirects and XML sitemaps must send consistent signals.
- Duplicate templates, thin location pages, empty listings, filtered URLs and soft 404s frequently create indexation problems at scale.
- Inspect rendered HTML, not just source HTML, when important content depends on JavaScript or API responses.
- Strengthen page groups with distinct intent, original evidence, useful internal links and clear ownership within the site architecture.
- Measure recovery by eligible URLs indexed, recrawl time, canonical agreement and organic impressions, not by submitted sitemap totals.
- Escalate to log analysis and specialist support when losses are large, persistent, template-wide or connected to migrations and rendering failures.
What Google not indexing a page actually means
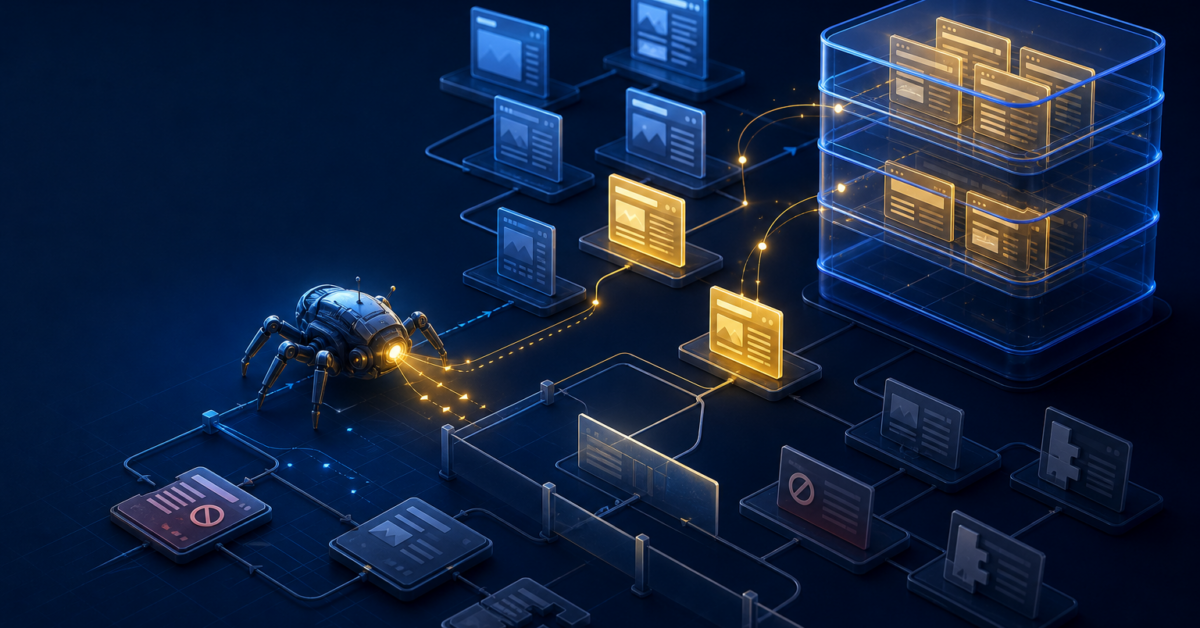
Indexing is the stage at which Google evaluates a fetched document and may add a selected version to its searchable index. It follows discovery and crawling, but it precedes ranking. Google provides no guarantee that a discovered, submitted or crawled URL will be indexed.
Crawled, currently not indexed means Googlebot fetched the URL but Google did not select it for the index at that time. Discovered, currently not indexed generally means Google knows the URL but has not yet crawled it. An indexable result in an auditing tool means only that the URL appears technically eligible. It does not predict Google’s final selection.
A page can also leave the index after previously appearing. That can follow a directive change, canonical reassessment, prolonged errors, duplication, reduced value, a migration problem or broader reevaluation of a page group.
Match the Search Console status to the likely cause
| Status or symptom | Most likely interpretation | First decisive test |
|---|---|---|
| Discovered, currently not indexed | Known URL awaiting crawl, often amid weak discovery, excess URLs or limited crawl demand | Check server logs, internal links and sitemap freshness |
| Crawled, currently not indexed | Fetched but not selected, commonly because of duplication, low information value, soft errors or processing delay | Compare the page with indexed pages serving the same intent |
| Duplicate, Google chose different canonical | Google considers another URL the stronger representative | Compare redirects, canonicals, internal links and sitemap URLs |
| Excluded by noindex | Google detected a page-level or HTTP directive | Inspect HTML and the X-Robots-Tag response header |
| Blocked by robots.txt | Crawling is prohibited, so Google may not inspect the page fully | Test the exact URL and required resources against robots.txt |
| Soft 404 | The server returns success, but the content resembles an error, empty result or unavailable item | Review rendered content and return a real 404 or 410 when appropriate |
| Indexed report and URL Inspection disagree | Reporting systems may be using different snapshots | Inspect the live URL, note the crawl dates and recheck later |
A decision framework for diagnosing the URL
- Confirm the preferred URL. Choose one exact protocol, hostname, path and parameter version. Test that URL rather than relying on a site search operator.
- Inspect it in Search Console. Record the status, last crawl, selected canonical, declared canonical, referring sitemap and whether crawling is allowed.
- Test the live response. Verify a stable 200 response for an indexable page. Follow redirect chains and inspect intermittent 403, 429 and 500 responses.
- Check indexation controls. Review meta robots, X-Robots-Tag, robots.txt, canonical tags and redirect behavior.
- Compare rendered output. Confirm that the title, main copy, structured data and links survive rendering without failed scripts, blocked resources or empty API responses.
- Test distinctiveness. Compare the page against its canonical, sibling templates and competing pages. Identify what information only this URL provides.
- Evaluate discovery. Confirm that relevant indexed pages link to it and that it appears in a clean, current XML sitemap.
- Diagnose the pattern. Segment affected URLs by template, status, publication date, directory and content type. A shared pattern is more actionable than one isolated URL.
After a material fix, request indexing for a small representative sample. If that sample remains excluded after recrawling, reassess the hypothesis before changing thousands of URLs.
Technical blockers to eliminate first
Inspect both the HTML robots meta tag and HTTP X-Robots-Tag. A noindex directive only works when Googlebot can crawl the resource and see it. Blocking the same page in robots.txt can prevent Google from observing a newly added or removed noindex directive.
Confirm that the preferred URL does not redirect, return an error intermittently, require authentication, trigger a firewall challenge or vary by user agent. Server protection that treats Googlebot as hostile can create sporadic failures that a browser test misses. Validate genuine Googlebot requests before allowing special network access.
Use 404 or 410 for permanently unavailable URLs without substitutes. A page that returns 200 while displaying no products, no results or a generic error can be classified as a soft 404. If a useful replacement exists, redirect directly to it. Avoid redirecting every removed page to the homepage.
For migrations, audit old-to-new mappings, redirect chains, canonical tags, internal links and XML sitemaps together. A partial migration can make Google alternate between URL versions.
Canonical conflicts and duplicate URL systems
Google treats redirects, rel canonical annotations and sitemap inclusion as canonical signals, with different strengths. These signals should identify the same preferred URL. A page that canonicals to itself but receives internal links through parameters, redirects elsewhere and appears under several sitemap URLs creates avoidable ambiguity.
Common duplicate systems include HTTP and HTTPS versions, alternate hostnames, trailing slash variants, tracking parameters, sorting and filtering URLs, print pages, syndicated copy, tag archives and repeated location templates. Decide which variants deserve independent search visibility. Consolidate true duplicates through redirects or canonicals, remove noncanonical variants from sitemaps and link internally to the preferred URL.
Do not canonicalize pages merely because they share a layout. Pages with genuinely different intent, inventory, local evidence or specifications may deserve separate indexing. Conversely, changing a city name across hundreds of otherwise identical pages rarely establishes independent value. Consolidation can improve the indexed proportion and focus crawling on URLs the business actually wants users to find.
When the real problem is page value
If access, directives and canonicals are correct, evaluate whether the page earns a separate place in the index. Google may crawl a technically valid URL and still treat it as redundant, unhelpful or error-like. Word count alone is not a useful threshold.
Ask five questions: Does the page answer a distinct query intent? Does it contain information absent from sibling pages? Is its main purpose clear without navigating elsewhere? Can users verify the author, business, method or evidence? Would consolidation create a better result?
Useful improvements may include original measurements, first-hand photographs, expert analysis, complete product attributes, local staff and service evidence, pricing context, comparison criteria, limitations and clearly maintained dates. For programmatic pages, require a minimum data threshold and suppress empty combinations. For old articles, merge overlapping pieces, redirect obsolete versions and refresh evidence rather than changing the publication date alone.
Scaled AI-generated or templated copy is not automatically excluded because of its production method. The risk arises when pages are unoriginal, inaccurate or created mainly to manipulate search results. Independent studies can reveal content patterns, but they do not prove that one factor causes Google to withhold indexing.
JavaScript rendering and content delivery failures
Google processes JavaScript through crawl, render and index phases. A 200 response is therefore insufficient if the initial HTML contains little content and rendering later fails. Use URL Inspection’s rendered output and screenshot, then compare them with a normal browser session.
Look for blocked script files, failed API calls, consent layers that conceal the page, infinite loading states, client-side redirects and robots directives inserted by JavaScript. Confirm that canonical tags remain stable after rendering. Important copy and links should be available in server-rendered or reliably rendered HTML rather than appearing only after interaction.
Test logged-out sessions, mobile output and cold cache behavior. Monitoring should include rendered content presence, not only uptime. A page can be technically online while its meaningful content is unavailable to crawlers.
Internal linking, crawl prioritization and log evidence
Place important URLs within a coherent hub-and-spoke structure. A service hub should link to legitimate service and location pages, while those pages should link back to the hub and to closely related resources. Descriptive anchors help users and crawlers understand each page’s entity and intent. Avoid creating thousands of orphan pages that exist only in an XML sitemap.
For large or rapidly changing sites, analyze server logs by Googlebot type, status code, directory and recrawl interval. Identify whether valuable pages receive requests while parameters, search results and duplicate archives consume activity. Crawl budget is usually not the primary concern for small sites, but URL waste becomes material on large inventories and publishing platforms.
External links are not a substitute for indexability, yet genuine references can improve discovery and demonstrate demand. Favor link-worthy original datasets, statistics pages, comparison assets and expert contributions. Link-intersect research, unlinked brand mention outreach and digital PR are defensible when they earn editorial citations. Purchased spam links and automated indexing services do not repair canonical, content or rendering defects.
A prioritized recovery plan and measurable KPIs
- Define the indexable set. Separate revenue, informational and support URLs from duplicates, filters, internal search results and empty pages.
- Repair hard blockers. Fix response codes, directives, robots rules, rendering failures and redirect loops.
- Align canonical signals. Standardize redirects, canonical tags, internal links and sitemap entries.
- Improve or consolidate weak groups. Add unique evidence where a separate page is justified. Merge or remove pages that compete for the same intent.
- Strengthen discovery. Add contextual links from indexed hubs and publish accurate last modification dates.
- Validate a sample. Request indexing for representative URLs and wait for a fresh crawl before scaling the remedy.
- Monitor by cohort. Compare templates and directories rather than reporting one sitewide percentage.
Track the percentage of eligible URLs indexed, median time from publication to first crawl, median time from crawl to indexing, declared versus selected canonical agreement, Googlebot success rates, soft 404 counts, organic impressions and the number of indexable orphan URLs. Do not count intentionally excluded pages as failures.
Consider specialist help when a migration causes broad losses, JavaScript output differs for crawlers, millions of URLs require crawl controls, or exclusions persist after verified recrawls. A credible engagement should produce evidence, testable hypotheses and cohort reporting, not a promise of guaranteed indexing.
What is proven, what is consensus and what remains uncertain
Proven through official documentation
Google does not guarantee indexing. Sitemaps assist discovery but do not compel inclusion. Noindex must be crawlable to be observed. Canonicals are signals rather than absolute commands. Duplicate content, soft 404s and JavaScript failures can interfere with crawling and indexing.
Strong practitioner consensus
Template-level clusters are usually more informative than isolated URLs. Practitioners frequently find that author archives, localization pages, filters and near-identical programmatic pages share exclusion patterns. Search Console reports can also lag behind URL Inspection. These are useful diagnostic observations, not confirmation of a hidden Google rule.
Still uncertain
Google does not publish a universal quality threshold, a fixed recrawl timetable or a complete weighting of canonical signals. Research into document-quality scoring supports the plausibility of quality-aware processing, but it does not disclose Google’s production systems.
For AI search, conventional indexation remains important for visibility in Google search surfaces, but indexing does not guarantee selection in AI Overviews or AI Mode. Bing, Copilot, ChatGPT and other systems have separate discovery and retrieval pipelines. Clear entities, self-contained answers, explicit evidence and stable source URLs improve extractability, but no markup or submission method guarantees an AI citation.
FREQUENTLY ASKED QUESTIONS
SEO Questions Answered
How long does Google take to index a new page?
There is no fixed timetable. Discovery can occur quickly, while crawling and indexing may take days or longer. Important factors include internal discovery, server reliability, site history, duplication and the page’s value. Check the last crawl date before assuming a quality problem.
Does requesting indexing guarantee that Google will index the URL?
No. URL Inspection can ask Google to recrawl an eligible URL, but it cannot force inclusion. Use it after a meaningful fix, not as a repetitive submission tool. If a freshly crawled page remains excluded, investigate canonicalization, duplication, soft 404 signals and content value.
Why is my sitemap submitted but the pages are not indexed?
A sitemap is a discovery and canonical hint, not an indexing command. Include only preferred, indexable URLs that return 200 responses. Remove redirects, noindex pages, duplicate variants and dead URLs. Ensure internal links and canonical tags support the same URLs.
Should I block a noindex page in robots.txt?
Usually not if you need Google to observe the noindex directive. Robots.txt can stop Googlebot from crawling the page and seeing that instruction. Allow crawling until Google processes noindex, while considering security and crawl needs separately.
Can a page be indexed without appearing for a site search?
Yes. Site search operators are incomplete diagnostic tools and can show changing samples. Use Search Console URL Inspection for the specific canonical URL, then review impressions in the Performance report. An indexed page may still have no meaningful rankings.
Should every filter, tag and location page be indexed?
No. Index a variant only when it serves distinct search intent and provides a complete, useful result. Empty filters, arbitrary combinations and near-identical location pages can dilute signals and consume crawling. Consolidate, canonicalize or exclude variants that lack independent value.
Can backlinks fix Crawled, currently not indexed?
Not by themselves. Legitimate links can improve discovery, context and demand, but they do not remove noindex directives, repair rendering or make duplicate content unique. Fix the underlying page and site signals before pursuing editorial references.
Why did previously indexed pages disappear?
Check recent deployments, robots directives, canonical changes, redirects, server errors and rendered content first. Then assess whether the pages became outdated, duplicated or substantially weaker than another canonical. Segment losses by template and date to distinguish a shared defect from normal fluctuation.
When should I delete, improve or consolidate an excluded page?
Improve it when it serves unique intent and can provide material value. Consolidate it when another URL already answers the same need more completely. Delete it with a 404 or 410 when it has no replacement or continuing purpose. Redirect only to a genuinely relevant substitute.
RESEARCH SOURCES
Sources and Verification
- Google Search Central, Crawling and indexing FAQOfficial explanation of crawling, indexing, common exclusion reasons and the absence of an indexing guarantee.
- Ahrefs, Crawled, currently not indexedIndependent practitioner explanation of the status and a practical troubleshooting process.
- Ahrefs Help Center, Page is not currently in our indexClarifies that a third-party crawler's index and technical eligibility are distinct from Google's index.
- Screaming Frog SEO Spider FAQPractitioner reference for crawler interpretation and the limits of technical indexability classifications.
- HTTP Archive, Web Almanac 2025Large independent dataset covering 16.2 million websites and 244 TB of data. Useful for web prevalence benchmarks, not proof of indexing causation.
- arXiv, Quality-aware document processing research2025 research applying semantic document-quality models to crawl prioritization. It supports a hypothesis, not a claim about Google's production system.
- Semrush, AI content ranking data studyAnalysis of 42,000 blog pages and 200,000 ranking URLs. Useful for content-pattern comparison but not causal proof of indexing outcomes.
- Zeo, Controlling site quality through excluded URL analysisPractitioner guidance on using exclusion patterns to identify template and site-quality problems.
- Reddit SEO community discussionCurrent community observations about indexing behavior. Anecdotal evidence only, included to identify possible diagnostic patterns.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Research sourceConsulted during live web research for this page.
- Google Search Central, Block Search indexing with noindexOfficial guidance on robots meta directives, X-Robots-Tag and why Googlebot must crawl a page to observe noindex.
- arXiv, LLM crawling and discovery research2025 research examining sitemap and update-frequency signals in page discovery for LLM crawling.
- Reddit AI Search Optimizers discussion on author pagesPractitioner discussion of template-level exclusions affecting author pages. Not evidence of a confirmed Google rule.
- Google Search Central, Canonical URL consolidationOfficial guidance on redirects, canonical annotations, sitemap signals and duplicate URL consolidation.
- Research sourceConsulted during live web research for this page.
- Google Search Central, Troubleshoot crawling errorsOfficial documentation covering crawl failures, duplicate content and soft 404 behavior.
- Google Search Central, JavaScript SEO basicsOfficial description of Google's crawl, render and index workflow for JavaScript pages.
SEOS.CO EXPERT MATCH
Ready to Find the SEO Partner That Can Win Your Market?
Tell us your market, goals and growth targets. SEOS.co will help narrow the field and connect you with a serious SEO partner built for the opportunity.